
  1 import requests,json,os,datetime,math,re
  2 from PIL import Image,ImageDraw,ImageFont
  3 #将评论展现在图片中
  4
  5 #字体区
  6 nor_font=‘C:/windows/fonts/simsun.ttc‘
  7 micro_font=‘C:/windows/fonts/msyh.ttc‘#微软雅黑
  8 times_font=‘C:/windows/fonts/times.ttf‘#times new Roman
  9 huawen_font=‘C:/windows/fonts/STXINGKA.TTF‘#华文行楷
 10 english_font=‘C:/windows/fonts/STXINGKA.TTF‘#英文的
 11 fangsong_font=‘C:/windows/fonts/simfang.ttf‘#仿宋
 12
 13 path_req_img=r‘C:\Users\HDWEN\Desktop\test\test1‘
 14 path=r‘C:\Users\HDWEN\Desktop\test‘
 15 def get_pic(user,url,comment,count,time,reply_user=None,reply_content=None):
 16     #将头像图片都设置为固定大小(1024*1024)
 17     with open(os.path.join(path_req_img,os.path.basename(url)),‘wb‘) as f:
 18         f.write(requests.get(url).content)
 19     img1=Image.open(os.path.join(path_req_img,os.path.basename(url)))
 20     img1=img1.resize((1024,1024),Image.ANTIALIAS)
 21     width1 = img1.size[0]
 22     height1 = img1.size[1]
 23     img1=img1.crop((0,0,width1,height1))
 24     # print(width1,height1)
 25     #计算文字需要的行数
 26
 27     if reply_user==None:reply_content=‘ ‘;reply_user=‘‘
 28     #评论区
 29     #comment
 30     ft=ImageFont.truetype("%s"%fangsong_font, 250)
 31     # 一行设置为50个字
 32     one_zh_width=ft.getsize(‘中‘)[0]
 33     width = 1500 * 8
 34     w1,h1=ft.getsize(user+comment)
 35     w2,h2=ft.getsize(reply_user+reply_content)
 36     print(w1,h1,w2,h2)
 37     line_w1=math.ceil(w1/(width-1100))+1
 38     line_w2=math.ceil(w2/(width-1400))+1
 39     line=line_w1+line_w2
 40     height = (line + 3) * 250
 41     # print(line_w1,line_w2,height)
 42     # 创建空白图片
 43     image = Image.new(‘RGB‘, (width, height), (255, 255, 255))
 44     draw = ImageDraw.Draw(image)
 45     #评论区
 46
 47     text1 = user+‘:‘+comment
 48     ft = ImageFont.truetype(‘C:/windows/fonts/simfang.ttf‘, 250)
 49     all_h=[]
 50     def multi_line(text, h=0):
 51         if width-1100 > ft.getsize(text)[0]:
 52             draw.text((1100, h * 250+50 ), ‘%s‘ % text, fill=‘black‘, font=ft)
 53             all_h.append(0)
 54         else:
 55             for i in range(1, len(text) + 1):
 56                 if width-1100 - 250 < ft.getsize(text[:i])[0] < width-1100:
 57                     draw.text((1100, h * 250+50 ), ‘%s‘ % (text[:i]), fill=‘black‘, font=ft)
 58                     h += 1
 59                     t = text[i:]
 60                     all_h.append(h)
 61                     multi_line(t, h)
 62
 63     multi_line(text1)
 64
 65
 66     #点赞区
 67     draw.text((width-2200,height-400),‘点赞:(%s)|回复‘%(count),font=ImageFont.truetype(fangsong_font, 250),fill=‘blue‘)
 68     #时间区
 69     dateArray = datetime.datetime.utcfromtimestamp(time)
 70     shift_time = dateArray.strftime("%Y-%m-%d %H:%M:%S")
 71     draw.text((1100,height-400),‘%s‘%shift_time,font=ImageFont.truetype(fangsong_font, 250),fill=‘gray‘)
 72     #回复区
 73     image.save(os.path.join(path,os.path.basename(url)), ‘jpeg‘)
 74     img3=Image.open(os.path.join(path,os.path.basename(url)))
 75     img3.paste(img1,(50,50))
 76     if reply_user!=‘‘:
 77         img=ImageDraw.Draw(img3)
 78         #若是分行的话就要参照评论第二行的高度了
 79         img.rectangle((1300,500,width,1000),fill = (250,240,230))
 80         h=max(all_h)+2
 81         text2 = reply_user+‘:‘+reply_content
 82         def multi_line(text, h):
 83             if width-1400 > ft.getsize(text)[0]:
 84                 img.text((1400, h * 250+50), ‘%s‘ % text, fill=‘black‘, font=ft)
 85             for i in range(1, len(text) + 1):
 86                 if width-1400 - 250 < ft.getsize(text[:i])[0] < width-1400:
 87                     img.text((1400, h * 250+50), ‘%s‘ % (text[:i]), fill=‘black‘, font=ft)
 88                     h += 1
 89                     t = text[i:]
 90                     all_h.append(h)
 91                     multi_line(t, h)
 92
 93         multi_line(text2,h)
 94         # img.text((1400,650),‘%s:‘%(reply_user),font=ImageFont.truetype(nor_font, 250),fill=‘blue‘)
 95         # img.text((1400+ft.getsize(reply_user)[0]+ 250,650),‘%s‘%(reply_content),font=ImageFont.truetype(fangsong_font, 250),fill=‘black‘)
 96         # print(len(text),one_line_len)
 97     img3.show()
 98     img3.save(os.path.join(r‘C:\Users\HDWEN\Desktop\pic‘,os.path.basename(url)))
 99
100 params =‘N/k4O/N6NXalQC6Rv9BW8PTzWfT5CNZadhKUGlbtvyv4Txkq6VA4hy9CsYGAukRmtMJ2fhEF0IuVTxYdrhmpkb6WkYO25h/RV0uDd6dC9W7wU8y1Jt3+HlIPnnqvZeEgUOM8DcUZKx6Br+YcWI6G3v7ZPSecMA90sWdNXb9DEZhtcZD+V2GCRQxp/vxFgepdy/KaT1P8mMZ4wNdW99PYWMVLNprGNuyc8/GgMnIYHWQ=‘
101 encSecKey =‘a1264cb1d89ebc410d9a6d7ebae75fd78798c66e17b05299fe7564b33edda38653454ee8ed240c1eb77b8d159478ff6d9cd3521943371a1dd682474a1218c30800090541d87f6cbde133c69158a4bf72141c48872ecd3248578079cc1be6e2fb6b0dc80749857d893eae0ab4f516794a11cc8e39210659e421a4a6f7a8f5cf4d‘
102 headers = {
103     ‘Cookie‘: ‘appver=1.5.0.75771;‘,
104     ‘Referer‘: ‘http://music.163.com/‘,
105     ‘User-Agent‘:‘Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36‘
106 }
107 data = {
108         "params":params,
109         "encSecKey": encSecKey
110     }
111 song_id=‘19189445‘
112 url=‘http://music.163.com/weapi/v1/resource/comments/R_SO_4_{}?csrf_token=63c8e79f67b0ee78ce7f3d38a5081b2e‘.format(song_id)#format里面填写的是歌曲的id
113 res=requests.post(url,headers=headers,data=data)
114 dict=json.loads(res.content)
115 # print(dict)
116 dicts=dict[‘hotComments‘]
117 # print(dicts)
118 for i in dicts:
119     user = i[‘user‘][‘nickname‘]
120     comment = ‘‘.join([t for t in i[‘content‘] if t !=‘\n‘])
121     count = i[‘likedCount‘]
122     url = i[‘user‘][‘avatarUrl‘]
123     time = int(str(i[‘time‘])[:-3])
124     reply=i[‘beReplied‘]
125     if reply==[]:
126         get_pic(user,url,str(comment),count,time)
127         print(i[‘user‘][‘nickname‘],‘:‘,comment,‘*****Count:‘,i[‘likedCount‘],i[‘user‘][‘avatarUrl‘],int(str(i[‘time‘])[:-3]))
128
129     else:
130         reply_user=i[‘beReplied‘][0][‘user‘][‘nickname‘]
131         reply_content=i[‘beReplied‘][0][‘content‘]
132         get_pic(user,url,comment,count,time,reply_user,reply_content)
133         print(i[‘user‘][‘nickname‘],‘:‘,i[‘content‘],‘对于这个评论的回复:‘,i[‘beReplied‘][0][‘content‘],‘Count:‘,i[‘likedCount‘])
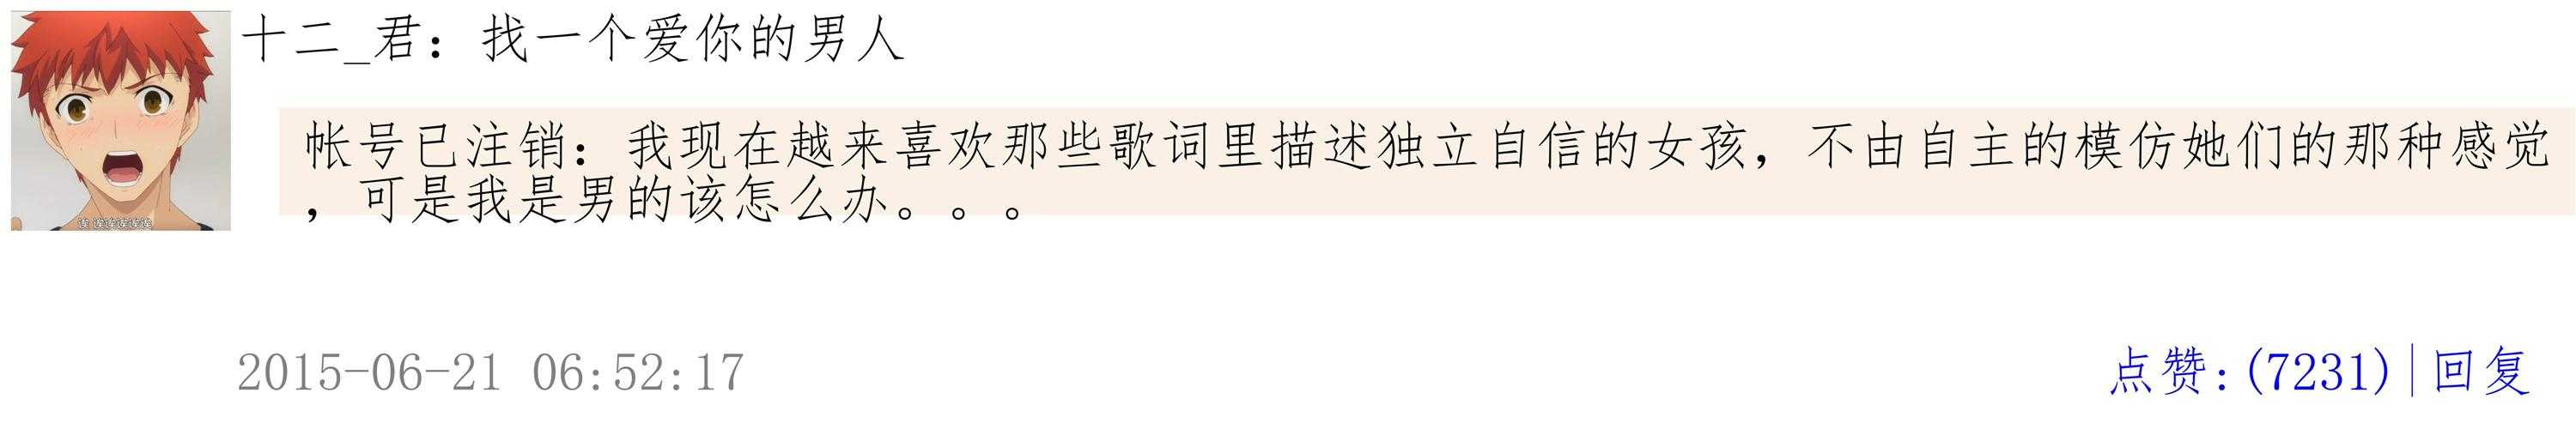
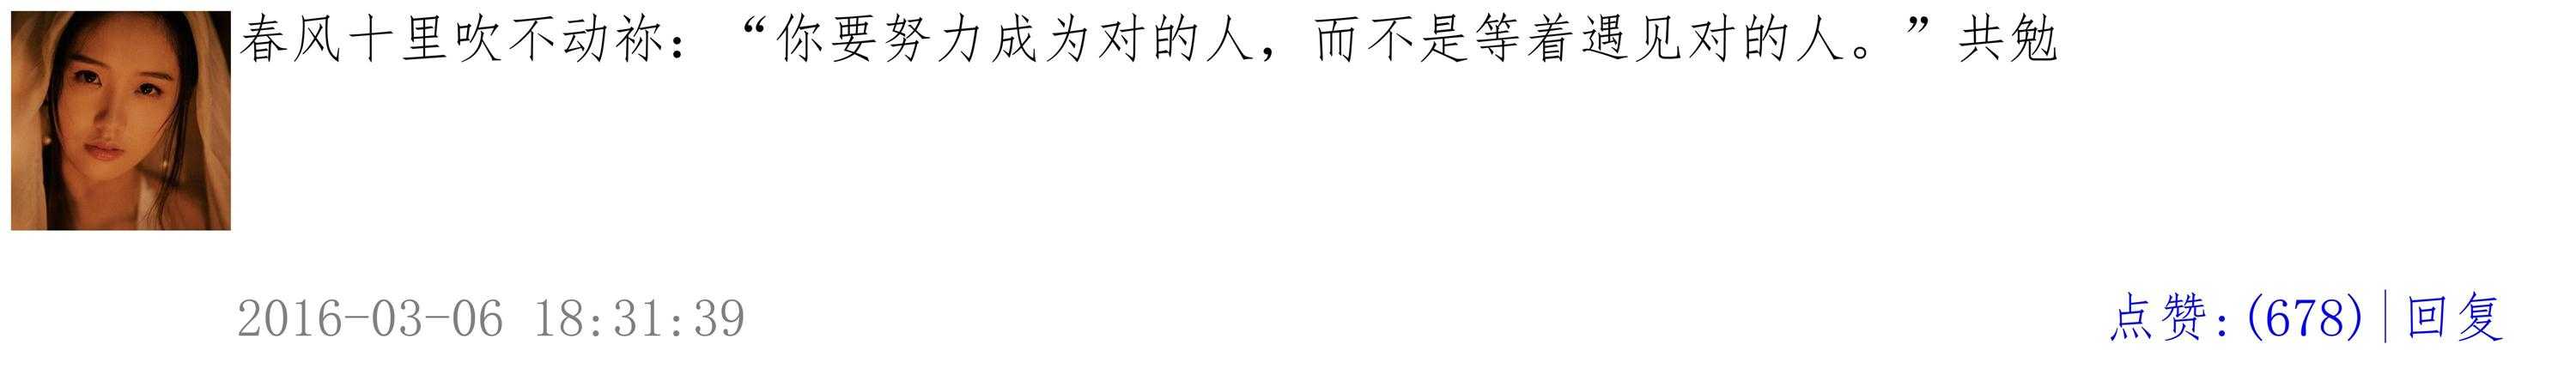
爬取网易热评做成网易云热门截图形式(给自己看的很乱有待更改)
原文:http://www.cnblogs.com/hdwen/p/7554122.html