
字数的信息(word)没有得到缺失
import xlwt
import requests
from lxml import etree
import time

all_info_list=[]
headers={
    #‘User-Agent‘:‘Nokia6600/1.0 (3.42.1) SymbianOS/7.0s Series60/2.0 Profile/MIDP-2.0 Configuration/CLDC-1.0‘
    ‘User-Agent‘:‘Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/55.0.2883.87 Safari/537.36‘
}
def get_info(url):
    html=requests.get(url,headers=headers)
    selector=etree.HTML(html.text)
    infos=selector.xpath(‘//ul[@class="all-img-list cf"]/li‘)
    for info in infos:
        title=info.xpath("div[2]/h4/a/text()")[0]
        author=info.xpath("div[2]/p[1]/a[1]/text()")[0]
        style_1=info.xpath("div[2]/p[1]/a[2]/text()")[0]
        style_2=info.xpath("div[2]/p[1]/a[3]/text()")[0]
        style=style_1+‘.‘+style_2
        complete=info.xpath("div[2]/p[1]/span/text()")[0]
        introduce=info.xpath("div[2]/p[2]/text()")[0].strip()
        word=info.xpath("div[2]/p[3]/span/text()")[0].strip(‘万字‘)
        info_list=[title,author,style,complete,introduce,word]
        all_info_list.append(info_list)
    time.sleep(1)
    #print(all_info_list)

if __name__==‘__main__‘:
    urls=[‘https://www.qidian.com/all?page={}‘.format(str(i)) for i in range(1,2)]
    for url in urls:
        get_info(url)
    #表头
    header=[‘title‘,‘author‘,‘style‘,‘complete‘,‘introduce‘,‘word‘]
    #建薄
    book=xlwt.Workbook(encoding=‘utf-8‘)
    #建表
    sheet=book.add_sheet(‘Sheet1‘)
    #写表头
    for h in range (len(header)):
        sheet.write(0,h,header[h])
    i=1
    for list in all_info_list:
        j=0
        for data in list:
            sheet.write(i,j,data)
            j+=1
        i+=1
book.save(‘qidianzuopin.xls‘)
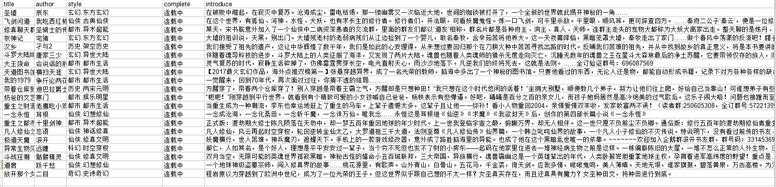
原文:https://www.cnblogs.com/lanbofei/p/8876121.html